Heterogeneous Compute
Covering model training, inference, content generation and industry applications — a heterogeneous compute system coordinating mainstream international GPUs with domestic AI chips.
Domestic AI Chips
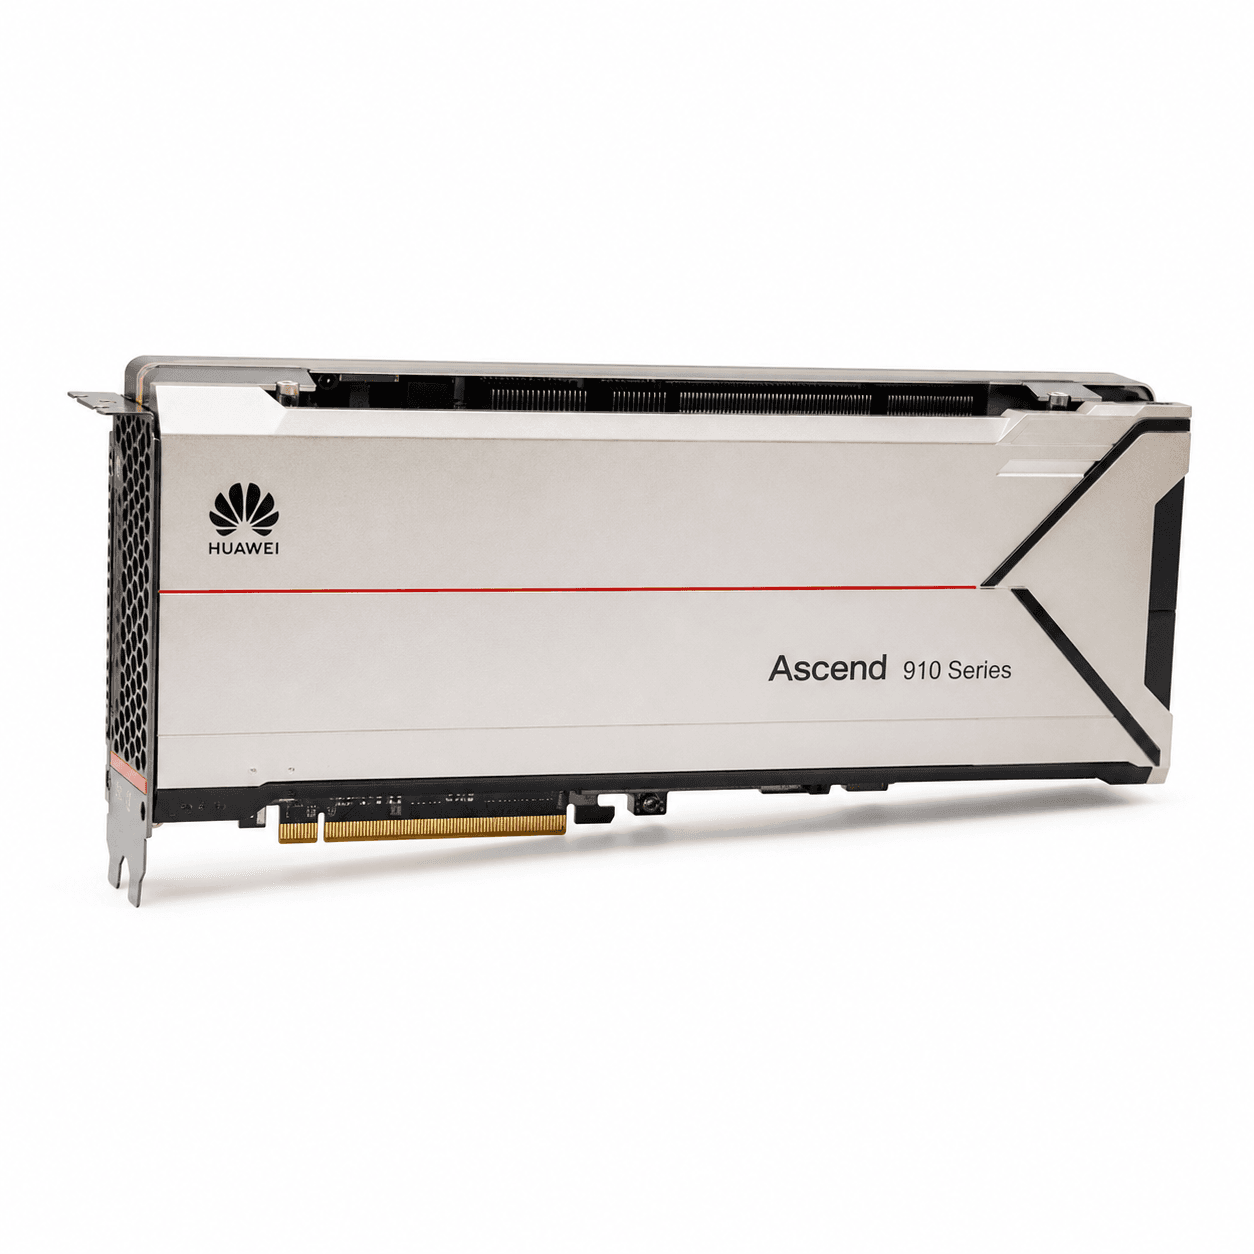
Ascend 910 Series
Domestic high-performance AI training & inference core
Scenarios
Features
- Full-stack AI infrastructure
- Cluster interconnect support
- Compatible with the CANN ecosystem
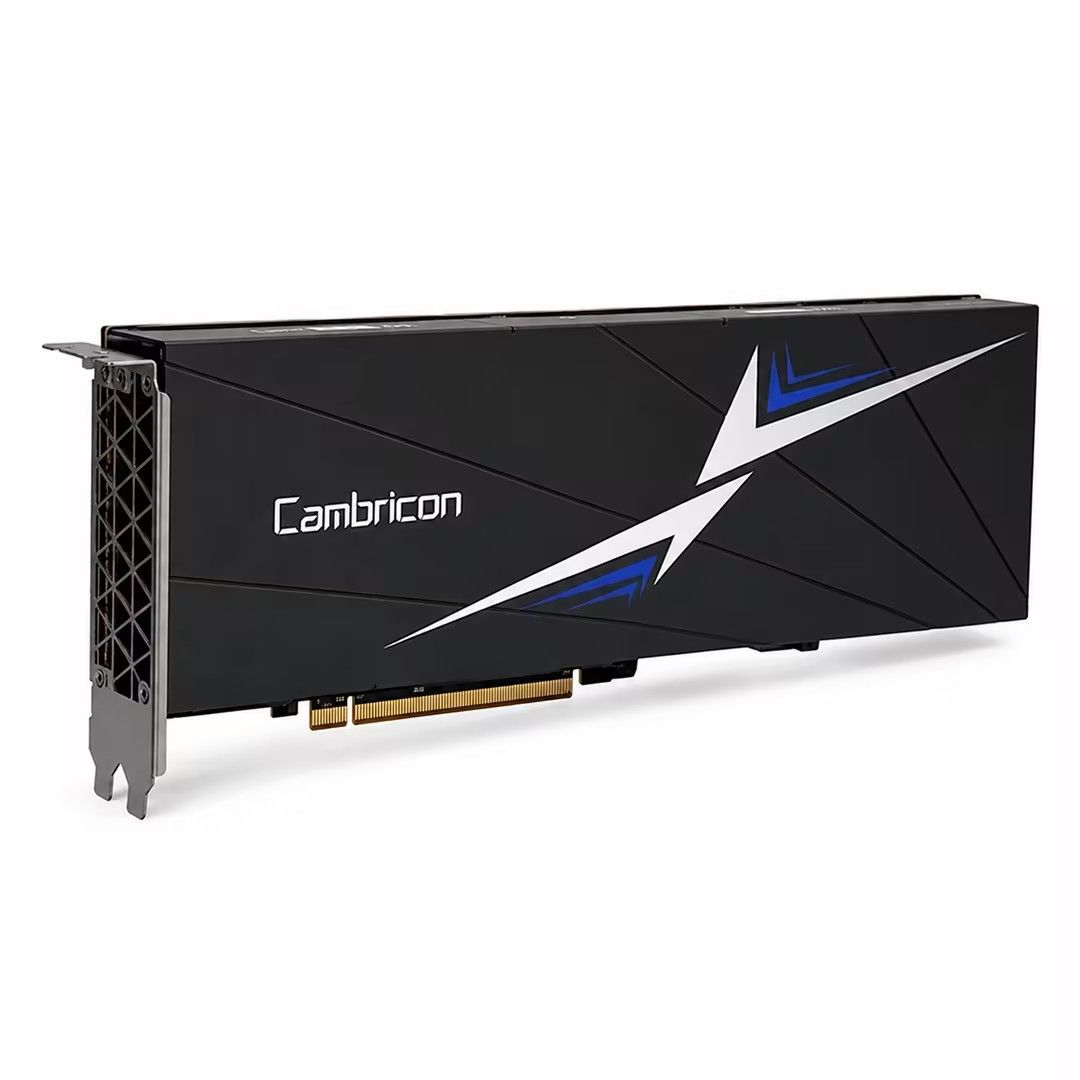
MLU370 Series
Domestic cloud-side train-inference AI accelerator
Scenarios
Features
- Unified training & inference
- Multi-card interconnect
- High-density deployment
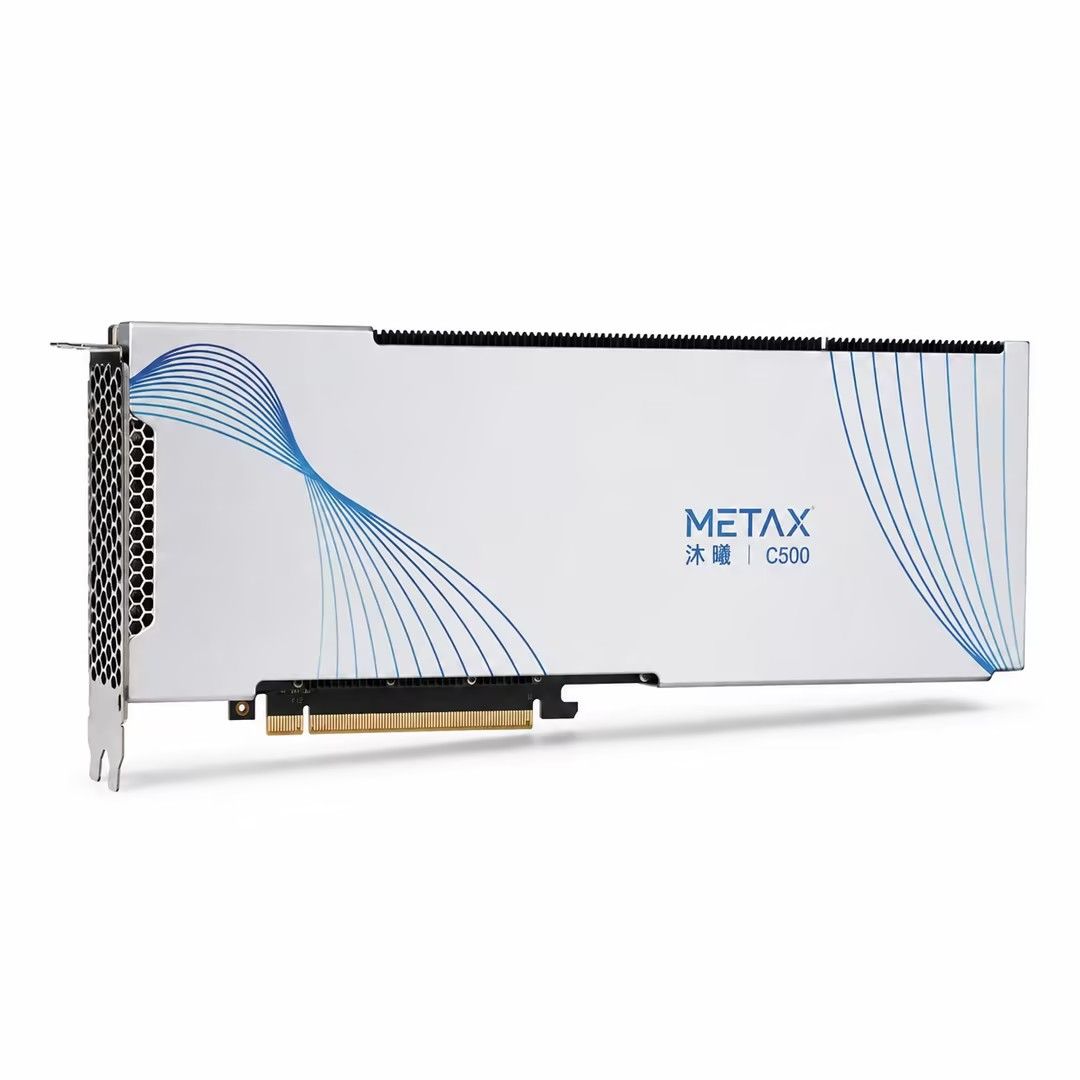
Xiyun C Series
Domestic cloud-side AI train-inference GPU accelerator
Scenarios
Features
- Fully in-house IP and instruction set
- Focused on the AI compute track
- Cumulative shipments of 25,000 units
- Strong deployment readiness
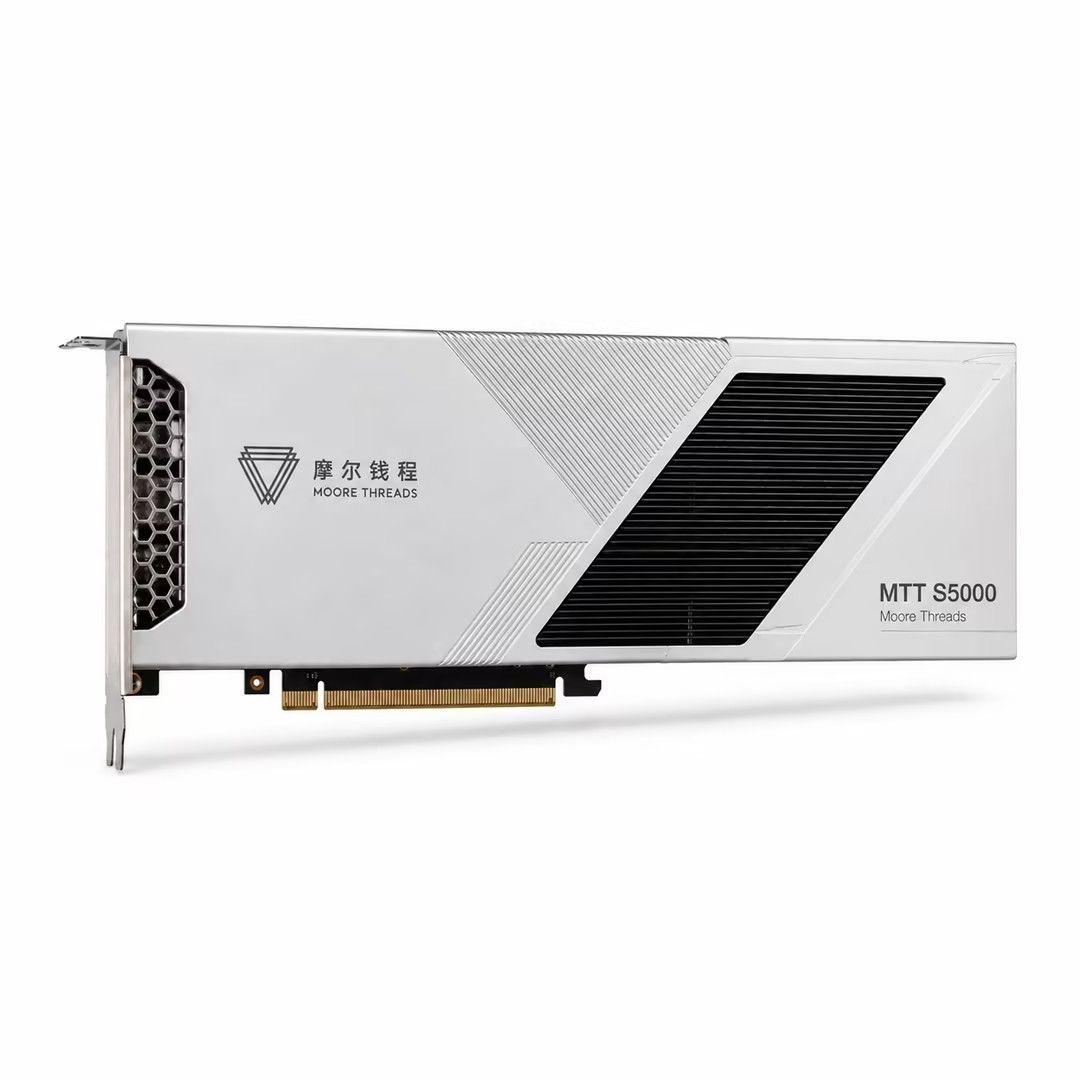
MTT S5000
Domestic flagship all-in-one AI train-inference GPU card
Scenarios
Features
- Built on the "Pinghu" architecture
- Full-precision compute from FP8 to FP64
- Up to 1000 TFLOPS dense AI compute per card
- Native support for PyTorch and other major frameworks
- Among the first to pass China's information security assessment
- Powers 10,000-card-class Kuaye clusters
- Training linearity up to 95%
Mainstream International GPUs
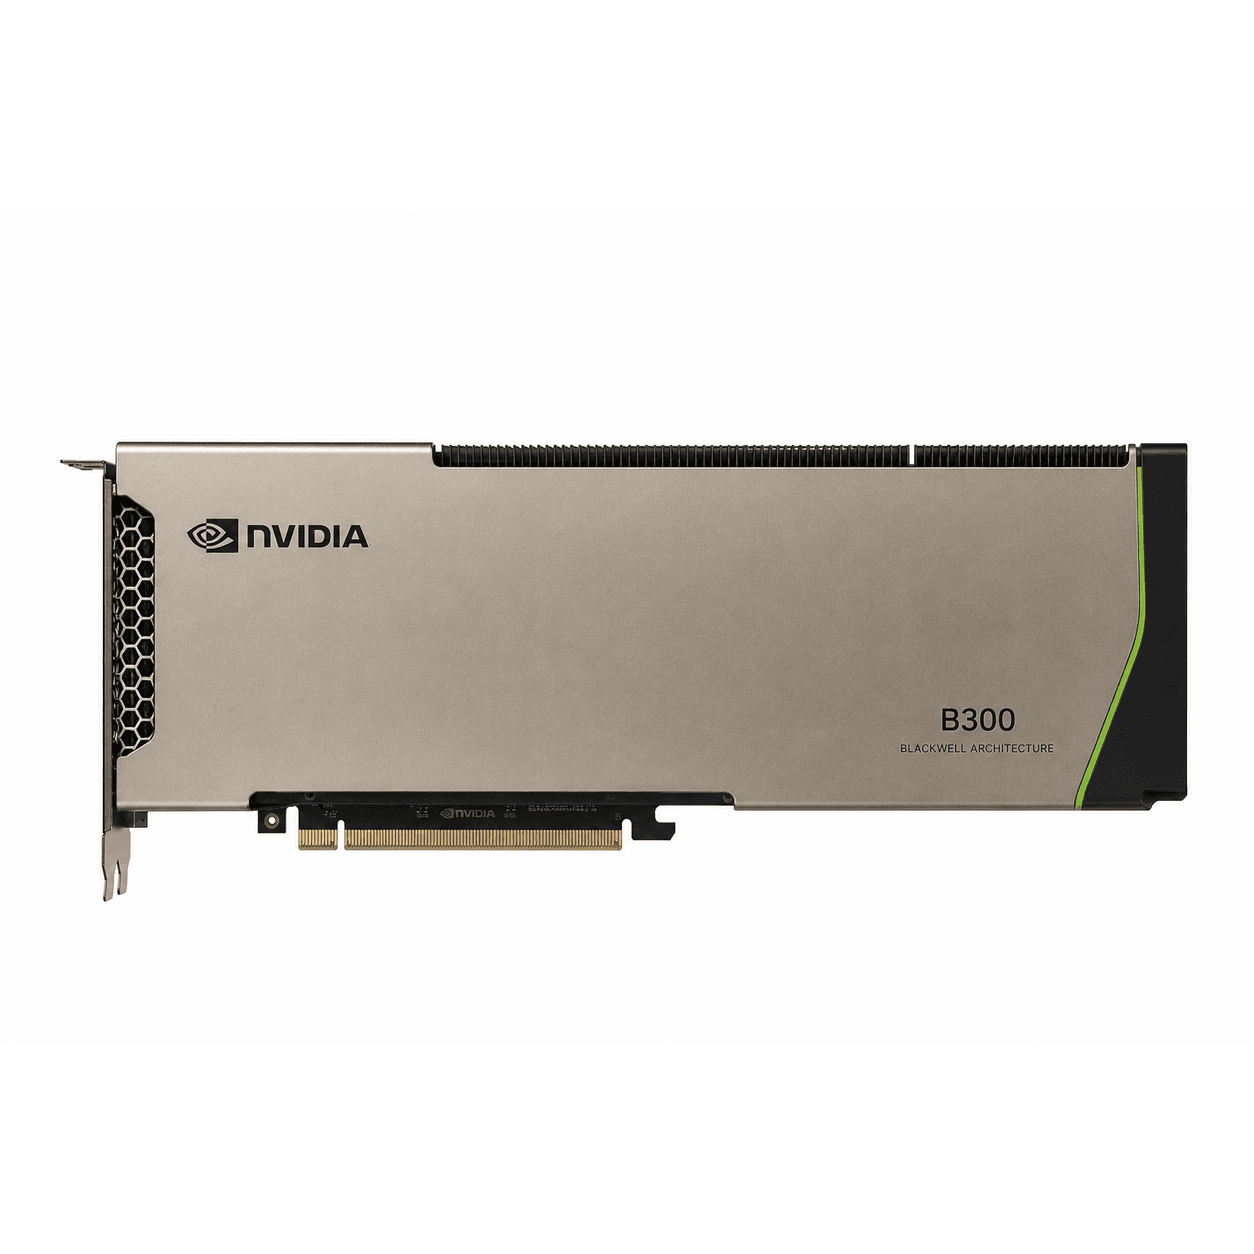
B300
Next-generation high-performance AI compute core
Scenarios
Features
- High compute
- Large memory
- High bandwidth
- Built for scaled clusters
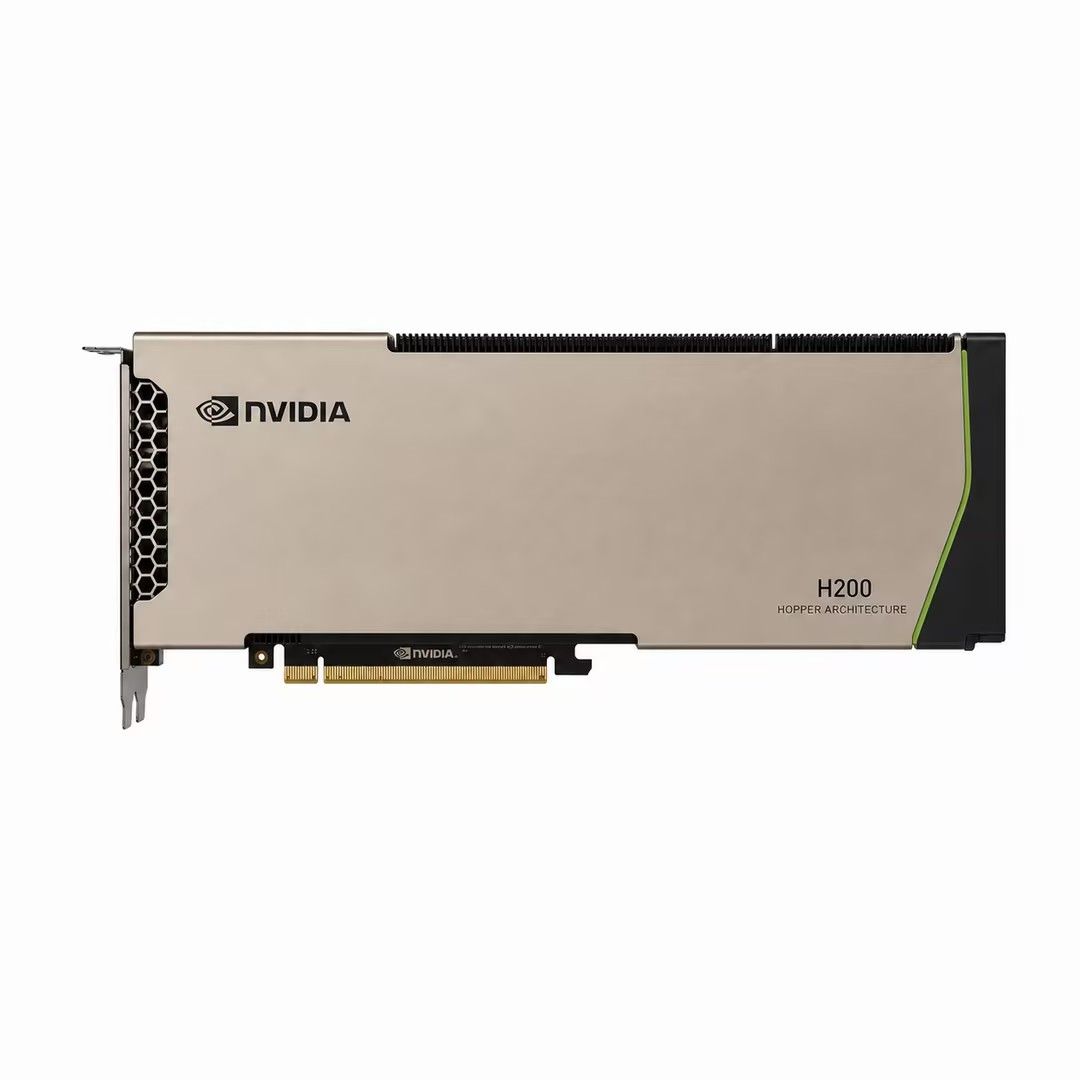
H200
Workhorse for large-model training & inference
Scenarios
Features
- Large-capacity memory
- High-speed interconnect
- Unified training & inference
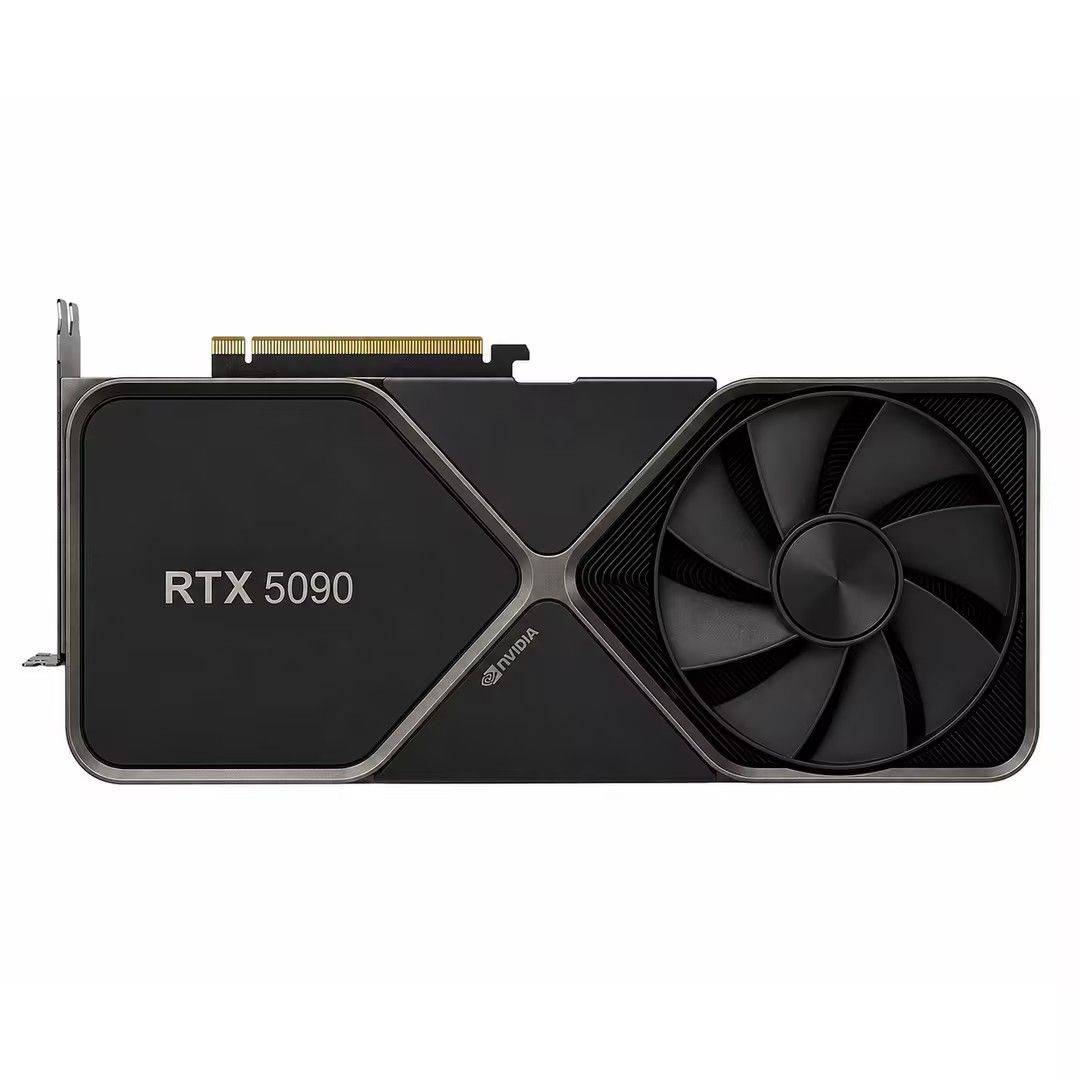
RTX 5090
AI inference & digital content generation node
Scenarios
Features
- Flexible deployment
- Efficient inference
- Broad application support
Chip Task Categories
Chips matched to training, inference, and graphics / content-generation tasks.
Training compute
Chips
B300, H200, Ascend 910 Series, MLU370-X8
Scenarios
Large-model pre-training, fine-tuning, scientific computing, multimodal training
Inference compute
Chips
H200, RTX 5090, Ascend 910 Series, MLU370-S4, Zhikai 100
Scenarios
Model serving, smart customer service, enterprise agents, vision recognition, real-time inference
Graphics & content generation
Chips
RTX 5090, MetaX graphics GPU series
Scenarios
AI image, AI video, digital humans, animation generation, 3D rendering
Device Numbering System
A unified numbering scheme linking model, spec, status and operations data.
NA-GPU-Type-Room-Rack-Seq
- NA-GPU-NV-A01-R03-008
- NA-GPU-AS-A01-R05-012
- NA-GPU-MLU-B01-R02-006
Type Codes
Linked Info
Ready to start your intelligent transformation?
Partner with NingAn AI to turn frontier AI into real business value.